Perspectives · Field notes
I killed my own AI outreach program. Here is what the data said.
Months of genuinely good AI-drafted outbound. Zero replies. Why the program died, what replaced it, and the lesson that does not automate.
Months of genuinely good AI-drafted outbound. Zero replies. Why the program died, what replaced it, and the lesson that does not automate.
Quality of output is not evidence of effectiveness. That is the whole lesson of this post, and it cost me several months of zero replies to learn it. If your AI outbound is producing good drafts and no results, the problem is not the drafts, and more of them will not fix it.
For several months I ran an experiment: an AI agent drafted every outbound sequence for a segment of my pipeline. Personalized, researched, staged for my review before anything sent. The drafts were good. Genuinely good. I approved them with light edits.
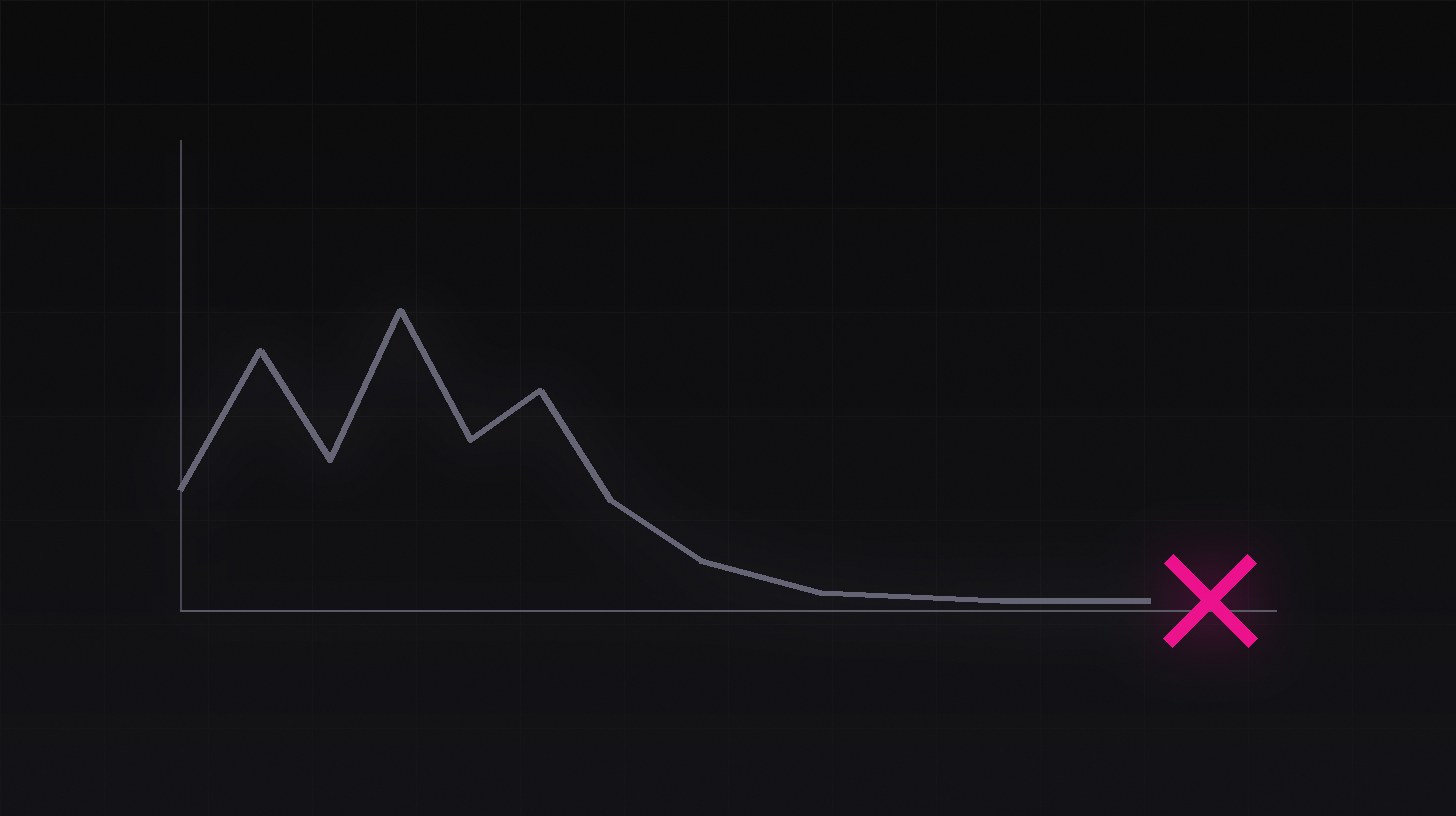
Zero replies. Not low response. Zero.
I gave it months because the drafts kept being good, and that is exactly the trap. The sequences were competent, relevant, and polite, and so is everyone else's now. My targets were senior executives whose inboxes are full of AI-personalized notes that all cite the same LinkedIn post. Mine read better. It did not matter. The channel itself had been strip-mined by the 80%, the same dynamic I unpack in the 80/20 rule of AI marketing.
I killed the program. Shut down the sequences, archived the campaign, and sat with the actual question: what do these people not get twenty times a week?
The answer was work. Not words about work. So I rebuilt the motion around give-to-get: a personalized diagnostic, produced by the same agent stack, showing each target something true and useful about their own company. How AI engines describe them. Where their positioning leaks. Something they can act on without ever hiring me. The first wave of seventeen went out in late September 2026, by email and LinkedIn, each one different because each company is different. That diagnostic now exists as a standing offer: the free GEO assessment on this site is the exact deliverable, and how AI engines describe your company explains what it measures.
Early days on results, and I will report honestly either way.
AI will happily keep producing forever. It has no instinct for futility. The program did not fail because the agent was bad. It failed because the strategy was wrong, and no volume of good drafts fixes a wrong strategy. Someone has to look at the scoreboard, overrule the machine's momentum, and redirect it at a better question.
That decision, the kill, is the job. It is the 20% that does not automate.
Less and less as a pure volume play. The personalization that stood out in 2024 is now the baseline in every executive inbox, so competent AI sequences increasingly produce nothing. What still works is leading with something the recipient can use: real analysis, a real diagnostic, real work.
Probably not because your copy is bad. More likely the channel is saturated with messages that look exactly like yours, produced by the same class of tools. Measure replies, not draft quality, and if the scoreboard says zero, change the strategy rather than the adjectives.
Outreach that opens by delivering something of standalone value, a personalized audit, assessment, or analysis the prospect can act on without hiring you, instead of asking for a meeting. It costs more per contact and is the point: it proves work instead of promising it.
Todd Henderson is a fractional CMO for founder-led companies, pairing 30 years of brand and marketing leadership with a deployed team of AI agents for market intelligence, outbound, reporting, content, and GEO. He is a Co-Founder of Defining.com, the naming and branding agency, and runs his fractional practice as a separate embedded-leadership engagement.
If you have an AI marketing motion running right now, ask the scoreboard question: is the output good, or is it working? If you are not sure, book a call. Or see the give-to-get for yourself: the free GEO assessment is the exact diagnostic I built after the funeral.